Track your ML experiments end to end with Data Version Control and Amazon SageMaker Experiments
less than 1 minute read
Data scientists often work towards understanding the effects of various data preprocessing and feature engineering strategies in combination with different model architectures and hyperparameters. Doing so requires you to cover large parameter spaces iteratively, and it can be overwhelming to keep track of previously run configurations and results while keeping experiments reproducible.
Full text here, and GitHub repository here
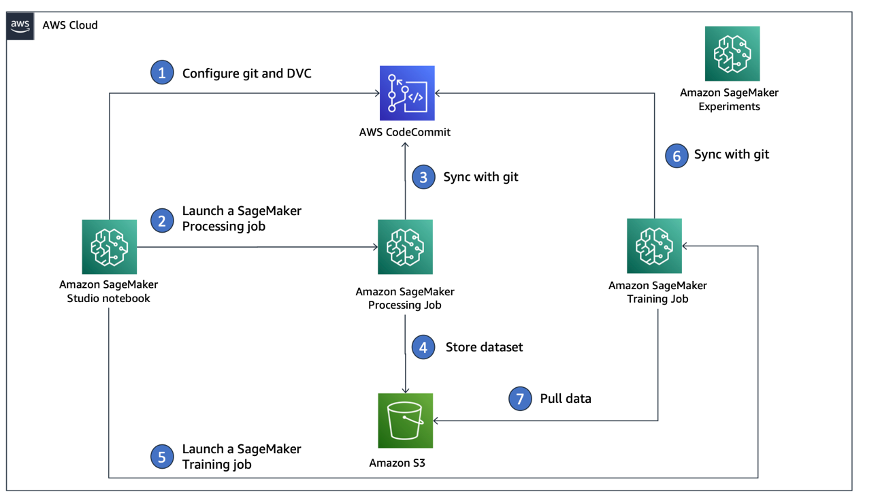
This post walks through how to use Data Version Control (DVC) alongside Amazon SageMaker Experiments to track data and code changes together with ML experiment metrics, providing end-to-end traceability for your ML workflows.
2026 update. SageMaker Experiments has since been superseded by managed MLflow on Amazon SageMaker AI as the experiment-tracking layer. The core idea — versioning data and code together with experiment metrics — still applies unchanged; for the current take on it, see the successor post: End-to-end lineage with DVC and SageMaker AI MLflow apps.