Track LLM model evaluation using Amazon SageMaker managed MLflow and FMEval
less than 1 minute read
In this post, we show how to use FMEval and Amazon SageMaker to programmatically evaluate LLMs. FMEval is an open source LLM evaluation library, designed to provide data scientists and machine learning (ML) engineers with a code-first experience to evaluate LLMs for various aspects, including accuracy, toxicity, fairness, robustness, and efficiency.
Full text here, and GitHub repository here
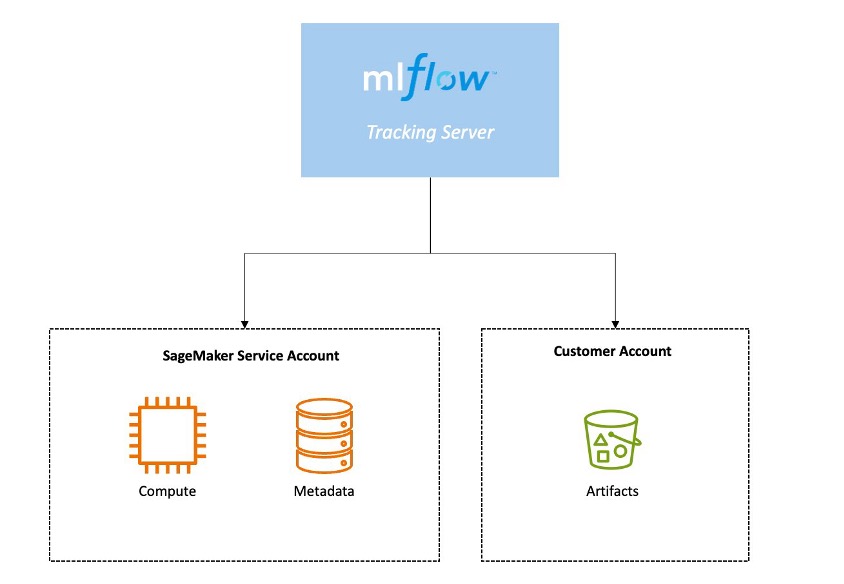
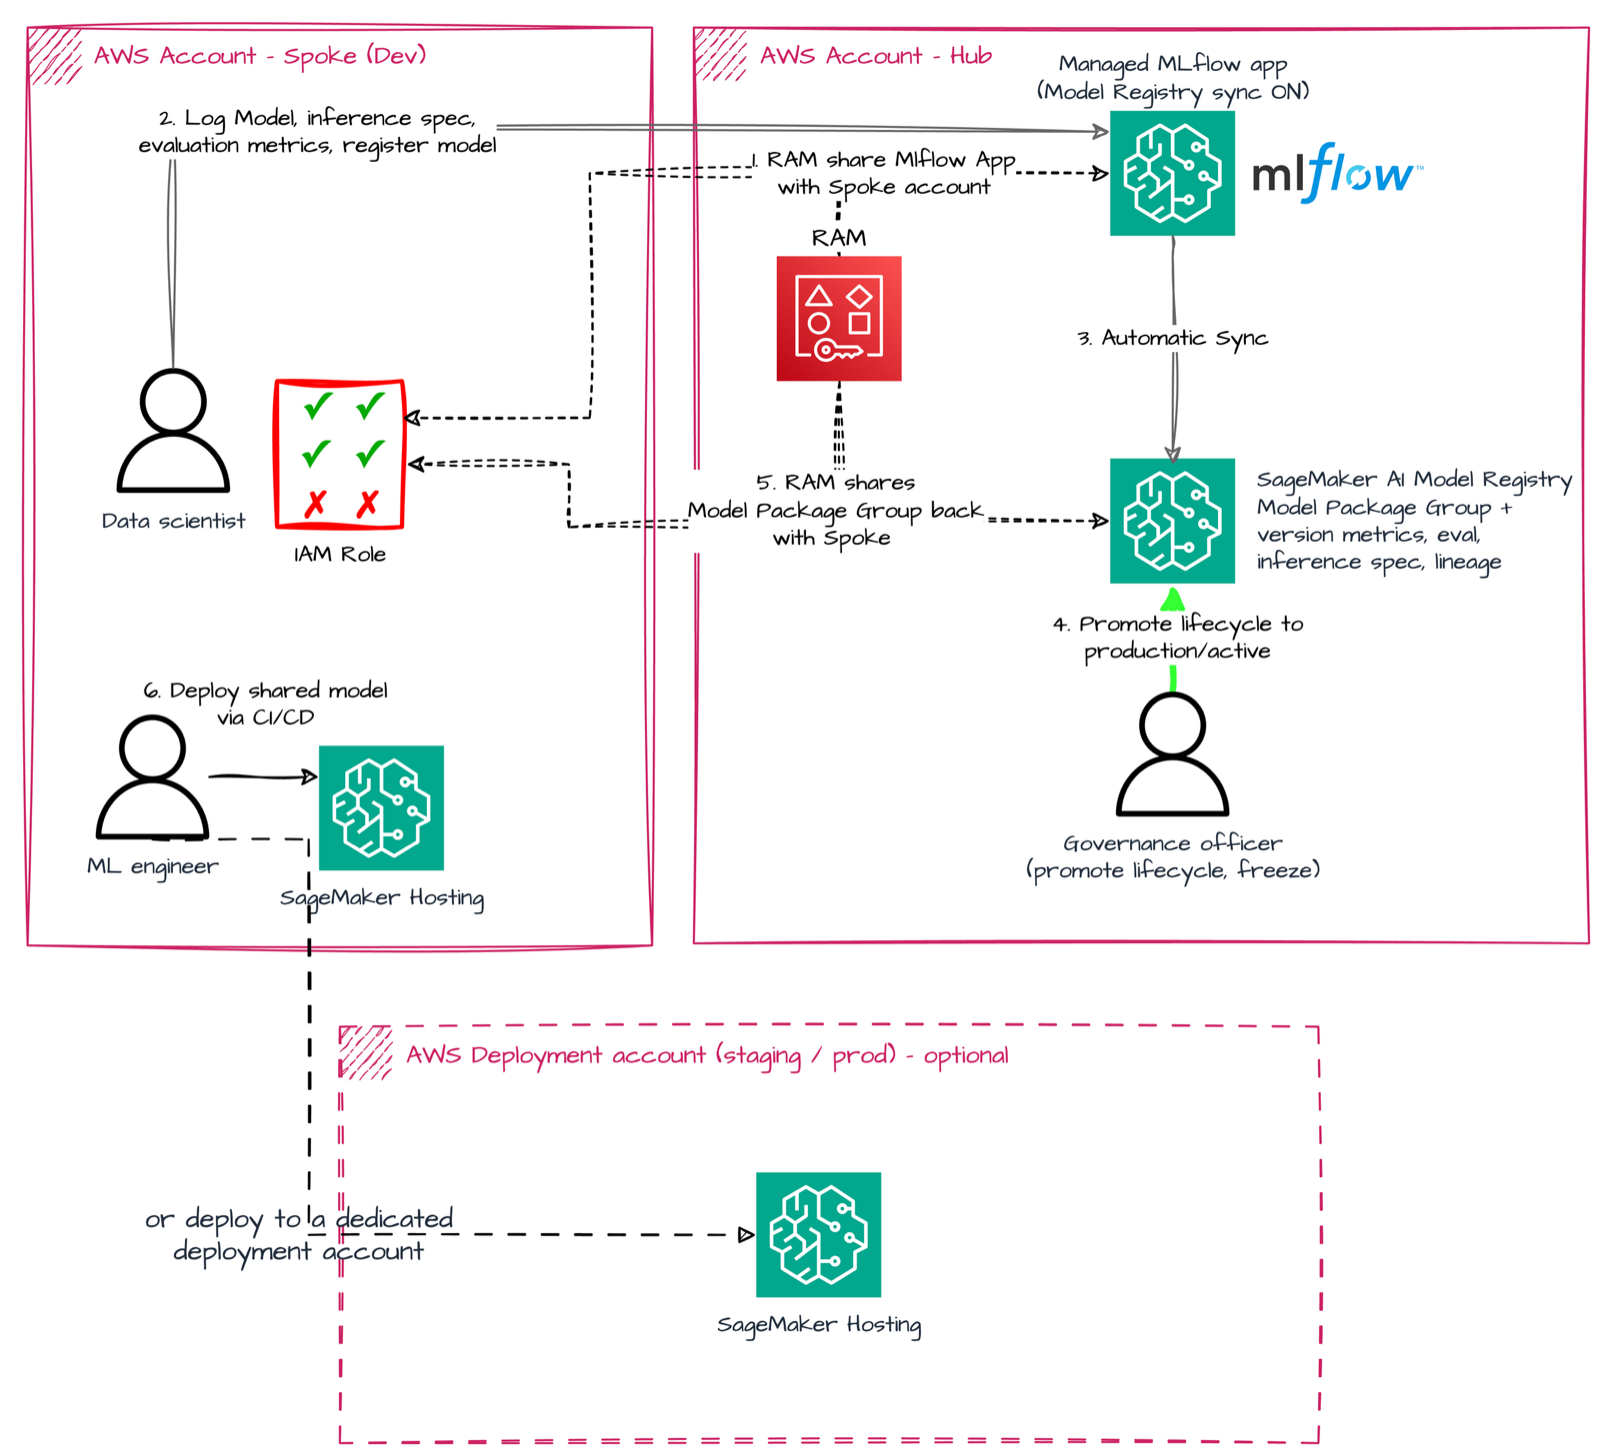
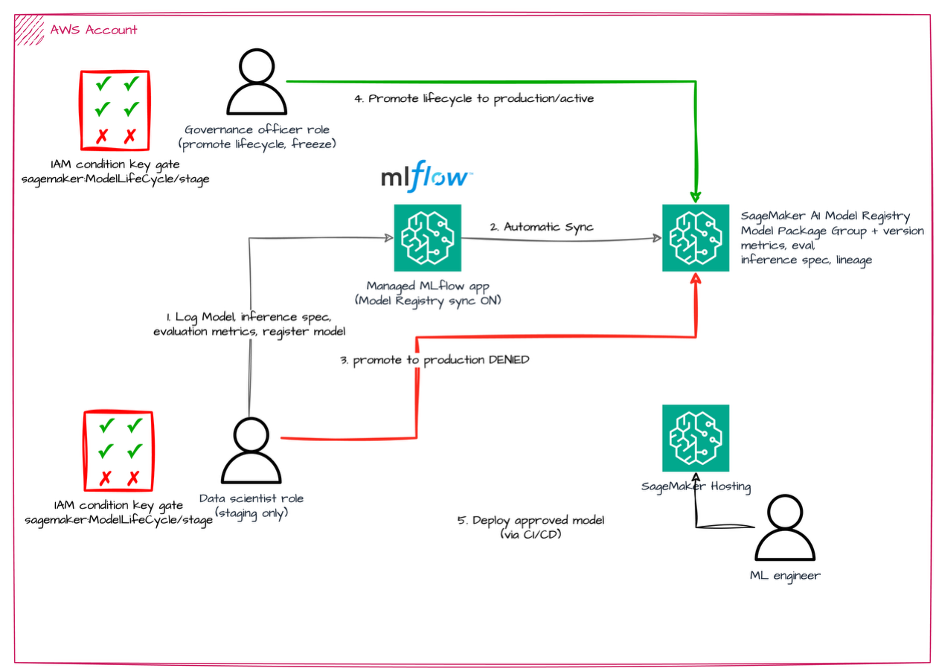
We demonstrate how to combine FMEval with Amazon SageMaker managed MLflow to track and compare LLM evaluation results, enabling systematic model selection and governance for your generative AI workflows.
Why I wrote this. LLM evaluation results tend to live in ad-hoc spreadsheets and notebook outputs, which makes model selection unreviewable. The point of this post is that evaluation metrics — accuracy, toxicity, fairness, robustness — deserve the same treatment as training metrics: logged, versioned, and comparable in an experiment tracker.